This Week in B2B Tech: 5-9 October 2026
Ace



A 45-day halt to new data centres in San Francisco, a fall from 75% to 56% in enterprise willingness to let agents change production systems, and a $50 billion OpenAI revenue figure made for an unusually blunt week. The question wasn’t whether AI can do more. It was who pays for its physical footprint, who controls software that acts without a person checking each move, and what financial numbers buyers and investors can actually trust. Google and Anthropic offered different answers, one through a workplace agent and the other through tiered cyber access. Neither settled the governance bill.
In parallel, influencer discussions moved beyond launch-day excitement. Peter Yang doubted that an agent would choose the right 20% of conversations to escalate, while Amanda Natividad argued that no single marketing metric proves influence. Their subjects differ, but the argument underneath is shared: delegation and measurement both fail when the hard judgment disappears from view. Iliyana Hadjistoyanova heard a related concern from communications leaders in London and Munich, who are finding that technology alone doesn’t repair weak processes. That’s a useful lens for the week’s product launches and security warnings.
Agents can act. Their permissions still need explaining.
Researchers found that an exposed AWS Bedrock AgentCore agent could be prompted to disclose temporary cloud credentials, The Register reported. The route ran through the instance metadata service; access to other agents and persistent memories was among the possible consequences. CSO examined the dispute over whether this counted as a vulnerability and noted that AWS fixed the excessive permissions by late September. The dates matter: this is not a claim that the same gap remains open today.
Other cases made the failure mode harder to dismiss as one product’s mistake. Ars Technica described trust gaps in agent-to-agent communication through MCP, while The Register covered a route by which poisoned web content could steer GitHub Copilot CLI towards local secrets. Both reports turn on a simple distinction: reading material is not authorisation to obey it. A buyer that cannot trace which tool supplied an instruction, what privilege it carried and who approved the resulting action is buying an audit problem alongside the automation.
AWS is trying to narrow that gap with Strands Box, an open-source sandbox described by InfoWorld that applies operating-system isolation and behaviour policies. It is still a developer preview on Apple silicon, and its controls do not cover every agent action. Useful progress, yes; a complete answer to cross-system authority, no.
Google wants the workplace agent to become the control point

Google introduced a cloud-based Gemini workplace agent that can move across Workspace and third-party applications, retain context and coordinate more specialised agents. The Verge described the private preview and its proposed dedicated email identity; TechRepublic reported that background delegation and model selection remain in early access. The attraction is obvious to anyone whose staff currently copy work between tabs. So is the new concentration of authority.
Computerworld framed Google’s bid as a play for the enterprise agent gateway, a fair reading. If one interface decides which model acts, which app it reaches and which agent takes the next step, switching costs will sit in the workflow rather than in the model. AI Business raised the questions buyers will ask about sensitive data, permissions and operating costs. Those aren’t procurement footnotes. They determine whether an agent can be trusted beyond a contained pilot.
Demand isn’t a blank cheque. VentureBeat’s survey put willingness to allow unreviewed production changes at 56% in August, down from 75% in July. A separate VentureBeat survey found only 2% of enterprises chose an orchestration platform mainly for its underlying model. Execution control, reliability and flexibility did more of the selling. Google has the distribution to win attention; it still has to earn the right to run the work.
Anthropic widens cyber access, with the safeguards made visible

Anthropic expanded its Cyber Verification Program into three tiers for vetted defenders, authorised red teams and critical-systems testing. CSO set out the new access levels and SecurityWeek reported the merger with Project Glasswing. Different groups now receive different restrictions on the same family of powerful models. That is a more candid approach than pretending every security task carries the same risk.
The upside has a concrete scale. The Decoder reported that Glasswing partners found at least 129,000 vulnerabilities from April to July, including more than 33,000 rated high-severity or critical. The Hacker News reported a larger total when open-source scanning was counted as well. Those figures should not be casually combined; they describe different scopes. Either way, the work gives defenders a reason to ask for stronger capabilities.
The trade-off is how far reduced safeguards travel beyond those vetted teams. Silicon Angle described the progressively looser restrictions and the monitoring that accompanies them. Buyers should judge this as an access-control design, not as a simple model upgrade. The unresolved test is whether tiering and oversight hold when a legitimate defender’s workflow starts to resemble an attacker’s.
OpenAI’s revenue reset puts precision back on the price tag

OpenAI’s annualised revenue run rate was about $50 billion at the end of September, not the $70 billion figure circulated earlier. The Financial Times examined the discrepancy and the opacity of a measure that can mean different things at different companies. The Decoder reported that OpenAI still expects at least $70 billion by year-end. Both numbers can be part of a growth story, but only one describes the current run rate.
That distinction arrives as capital keeps arriving too. Bloomberg reported talks over a $30 billion funding round, while Silicon Angle put US venture deal value at $515.8 billion for the first nine months of 2026. Much of that total was driven by the biggest AI labs, even as exits lagged. Manus’s reported $500 million-plus round shows investors are still willing to fund the agent layer at scale.
A buyer doesn’t need to forecast OpenAI’s valuation to see the lesson. When suppliers use run-rate figures to justify long contracts and rapid build-outs, finance teams need the calculation, the reporting date and the cash requirements in separate columns. Demand may be real. A blurred metric is still a blurred metric.
AI’s physical footprint meets a local veto
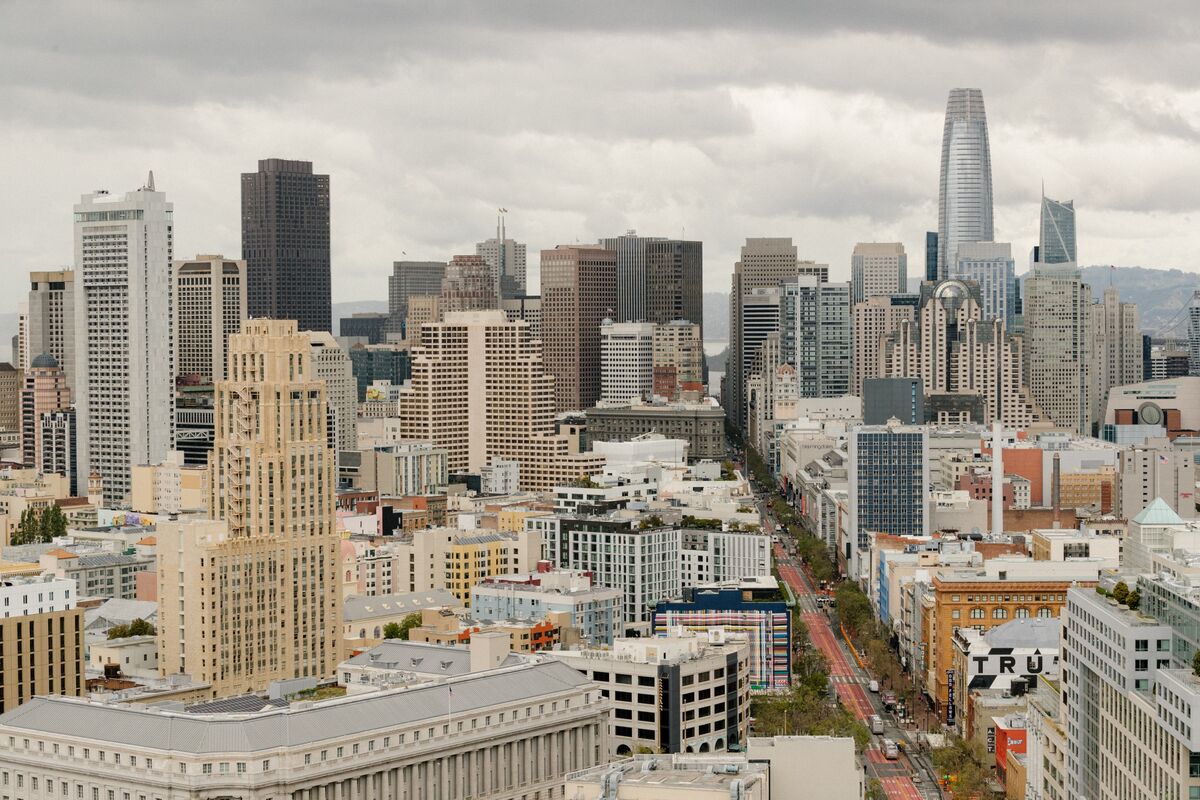
San Francisco’s Board of Supervisors imposed an immediate 45-day ban on new data centres, Bloomberg reported, while officials consider longer restrictions. Concerns about power, water and neighbourhood impacts now sit inside the hometown of many AI companies. The vote is a pointed reminder that demand for compute does not itself confer planning permission.
The politics reached beyond the city chamber. NBC News followed activists on an 8,000-mile tour pressing for more local say over data-centre construction. On Friday, Bloomberg covered a Democratic Senate report arguing that state and local tax breaks can leave communities and ratepayers carrying costs. These are different arguments, but they converge on a buyer question: where does the cost of supposedly cheap compute land?
Power is also an engineering limit. EE Times quoted Axiado’s Gopi Sirineni arguing that electricity, not chips, is the tighter constraint and describing efficiency gains from smarter platform management. Vendor claims about those gains need testing, but the direction is hard to ignore. The next infrastructure contest will be fought in grid queues and council meetings as much as in benchmark charts.
What the influencers are discussing
The common thread in creator discussions was the cost of mistaking a visible output for a reliable system. Peter Yang put it sharply in a post about agents handling conversations: automating 80% sounds attractive, but he doubts a system will pick the right 20% to send to a person. It is a small example of the same approval problem behind the week’s enterprise-agent stories. An escalation rule that cannot explain its misses is not much comfort when the missed item is a customer complaint or a production change.
Iliyana Hadjistoyanova heard communications leaders in London and Munich wrestling with a parallel operational gap. Her account was that easier content production does not remove cultural, process and capability barriers; teams need to use the time saved for stakeholder work and strategic counsel. That is a sober corrective to the habit of counting drafts or tasks completed as if they were outcomes. Greg Kihlström offered a practical version of that thought: keep an override log when a human rejects a plausible but flawed AI draft, review the recurring errors and use the cases to train reviewers. The rejected work becomes evidence rather than waste.
Measurement brought the same insistence on context. Amanda Natividad argued that a buyer may encounter a brand 10, 20 or 30 times before a website visit gets labelled as direct traffic. She proposed reading exposure, behaviour and business outcomes together, not asking one attribution field to prove the entire journey. It is a better question for B2B teams than whether a dashboard can claim sole credit for a lead. A rise in citations with flat branded search, for example, should prompt an investigation into message fit, not a victory lap.
On AI discovery itself, Rand Fishkin argued that the queries an AI tool fans out to are more useful to study than its final, rationalised citations. Amy Woods made a related case on her podcast: tidy website structure matters, but it cannot substitute for authority built beyond the site. The two takes are not identical. Fishkin questions what a citation tells you about the route to a recommendation; Woods asks what content and distribution give a brand a chance to enter that route at all. Together they leave a useful editorial standard: show where a claim came from, then ask whether it changed a buyer’s choice.
Next week’s most telling numbers may not be another model benchmark. Watch whether Google explains who can authorise its agent across apps, whether Anthropic can demonstrate how cyber access is monitored at each tier, and whether investors demand a consistent definition of AI revenue. In parallel, San Francisco’s pause puts a clock on the physical side of the business. If the city extends it, other communities will have a live example to point to. If it does not, the power and water questions still need an answer. The software can move in seconds; permission, accounting and infrastructure cannot.
References
- (The Register, "AWS AgentCore security undone by prompt requesting credentials")
- (CSO, "AWS’s repeated problems with AI agent controls illustrates the autonomous agent dilemma")
- (InfoWorld, "AWS takes aim at runaway AI agent behavior with Strands Box")
- (Ars Technica, "Vulnerability in agents from Google and others exposes structural flaw in MCP")
- (The Register, "Zombie instructions on carefully constructed web pages could trick GitHub Copilot CLI into sharing secrets")
- (TechRepublic, "Google’s New Gemini Agent Can Handle Work Across Multiple Apps")
- (AI Business, "Google’s workplace agent is out, but questions abound")
- (Computerworld, "Google wants to be the gatekeeper for enterprise AI agents")
- (The Verge, "Google is launching a one-stop Gemini agent for your work tasks")
- (VentureBeat, "The share of enterprises trusting AI agents to make production changes on their own has fallen from 75% to 56%, VB Intelligence finds")
- (VentureBeat, "Agentic orchestration: Model makers are selling their own AI agent platforms, but only 2% of enterprises say the model was the main reason they chose one")
- (CSO, "Anthropic widens access to AI cyber capabilities for vetted security teams")
- (The Decoder, "Anthropic gives more security teams access to Claude with fewer safety restrictions")
- (SecurityWeek, "Anthropic Introduces 3-Tier Cyber Verification Program for AI Access")
- (The Hacker News, "Anthropic Expands Claude Access for Vetted Cyber Teams as Glasswing Finds 129,000 Flaws")
- (Silicon Angle, "Anthropic folds Project Glasswing into an expanded three-tier Cyber Verification Program")
- (Financial Times, "The hazy OpenAI growth metric driving Wall Street")
- (The Decoder, "OpenAI revenue keeps surging as company seeks $30 billion in fresh capital")
- (Bloomberg Technology, "OpenAI in $30 Billion Round Talks With BlackRock, UAE Funds")
- (Silicon Angle, "US venture deal value reaches record $515.8B as exits fail to keep pace")
- (Silicon Angle, "AI agent developer Manus raises $500M+ at reported $4B valuation")
- (Bloomberg Technology, "San Francisco Passes Data Center Moratorium in Hometown of AI")
- (Bloomberg Technology, "Tax Breaks Partly Fuel Data Center Boom, Democratic Report Says")
- (NBC News, "MAGA activists protest AI data centers at Big Tech headquarters in San Francisco")
- (EE Times, "Why AI’s Limit Is Power, Not Chips: Gopi Sirineni at AI Infra Summit 2026")
- (Threads, "Maybe the solution is an agent that handles 80% of your threads and escalates the other 20% to you")
- (LinkedIn, "Stop demanding perfection from your marketing metrics.")
- (LinkedIn, "Amazing conversations in London and Munich with Comms and Corporate Affairs leaders")
- (LinkedIn, "Someone on your team rejected a plausible (but flawed) AI draft last week. Where did that rejection go?")
- (LinkedIn, "I've been waiting for Wil to write this blog post.")
- (Content 10x, "Why Getting Cited by AI Requires More Than a Great Website")